Introduction
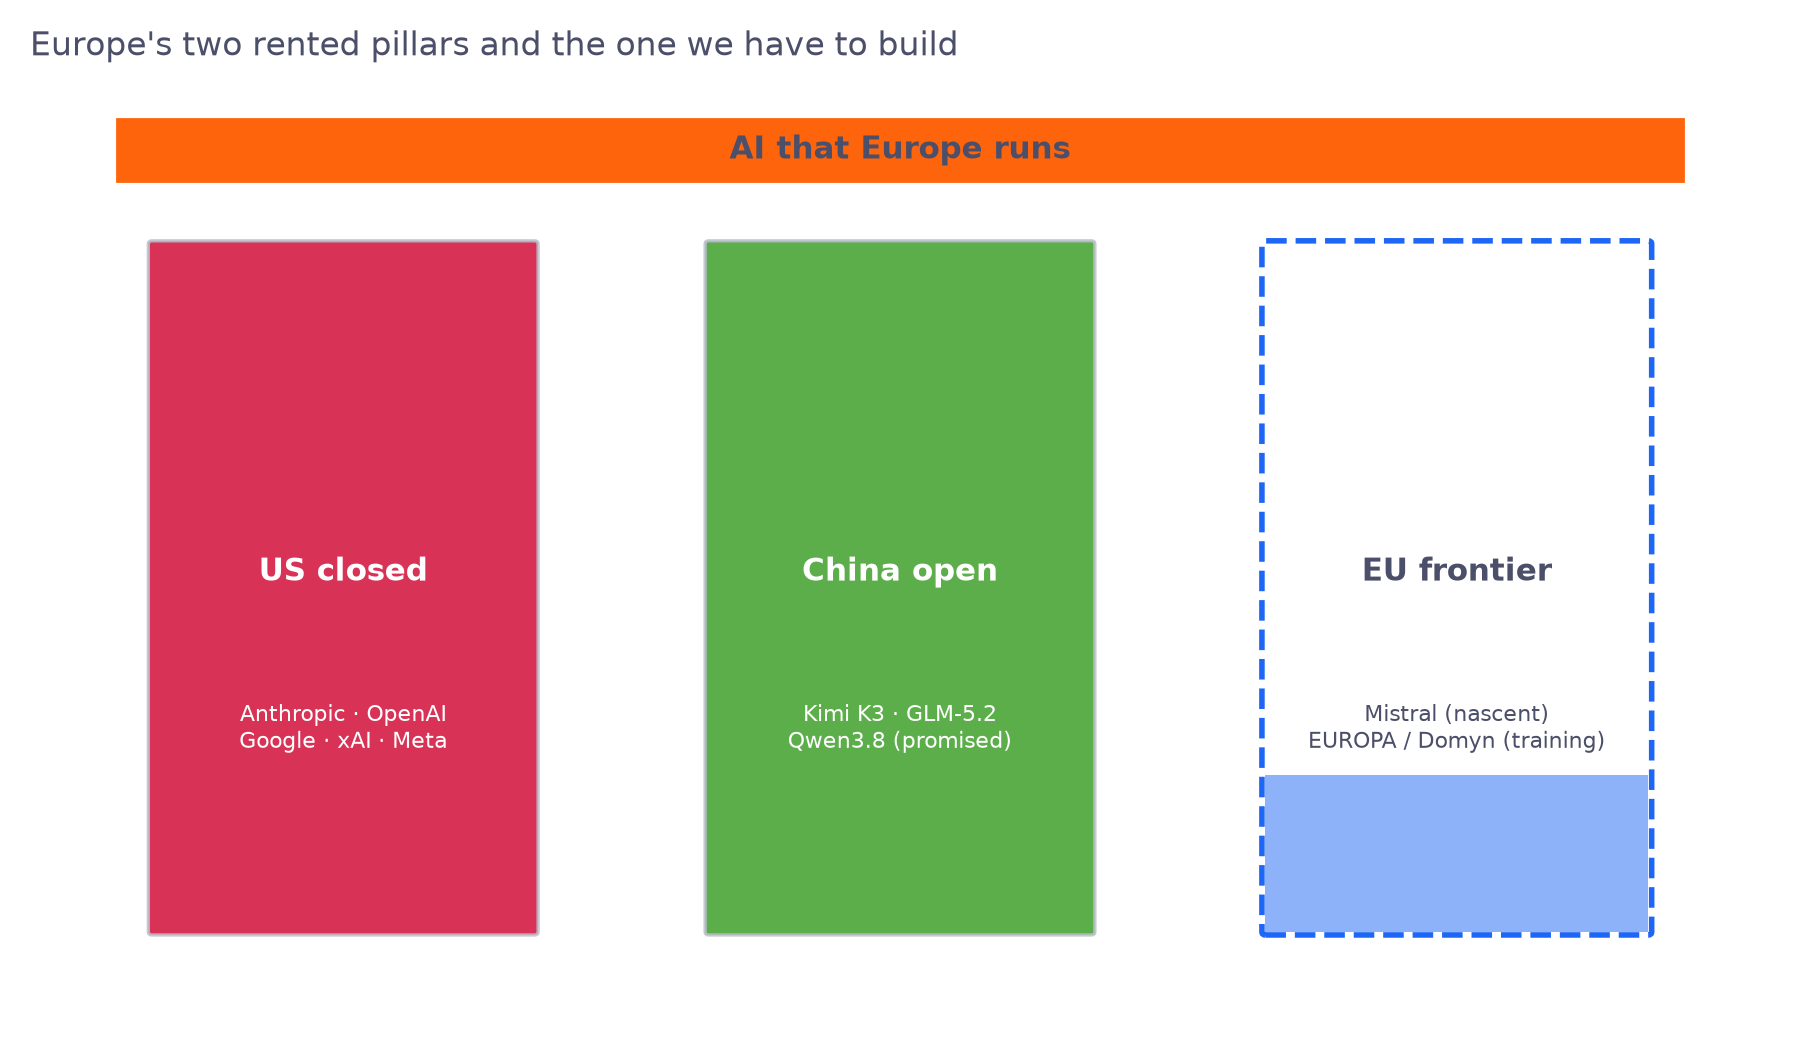
I have written about Europe’s AI sovereignty problem four times now, and every time I land in the same uncomfortable place. The two pillars Europe leans on (the closed US frontier and the open Chinese weights frontier) are both rotting, and the continent I live in still has no pillar of its own.
Each post made me restate the same facts, updated. Who shipped what this week. Which weights slipped behind an API. Which score moved. After the third pass I noticed I was doing something a blog post is bad at: keeping a running tally.
So this is the running tally. A living scoreboard. I will update it every time a frontier model lands, an AA index version bumps, or a set of weights quietly moves behind an endpoint. The date at the top of the scoreboard section tells you when I last touched it.
If you want the long argument for why this matters, read the two-pillars posts first (Green 2026a, 2026b). This page is the scoreboard. The argument lives there.
The two pillars, restated in one paragraph
Europe runs its frontier AI on two pillars we do not control. Pillar one is the closed US frontier (Anthropic, OpenAI, Meta, xAI, Google) accessed through APIs whose terms can change overnight based on a government we have nothing to do with. Pillar two is the open Chinese weights frontier (Kimi, DeepSeek, the Qwen open line, and the GLM line) which ships real weights today but ships them from a jurisdiction consulting on restricting overseas access to its most advanced models (The Next Web 2026). Both pillars can be pulled. We saw pillar two wobble in slow motion when Qwen3.8-Max launched API-only with weights “promised within days”, watched it partly reset on 2026-08-13 when the 2.4T-A95B weights landed on HuggingFace, watched it wobble again when Z.ai shipped GLM-5.3 API-first and delayed the weights over the model’s own cyber capability, and then watched the promise kept in full: the Flash tier landed open on 2026-08-26, and the full 5.3 weights landed on 2026-08-28, two weeks to the day after the API launch, on the schedule Z.ai named up front (Z AI 2026a, 2026b). We saw pillar one’s political risk go from theoretical to concrete when Anthropic tried corporate self-regulation for military use and got punished so publicly that no rational actor will try it again (Anthropic 2026a). This round the scoreboard grew a European version of exactly that. Spain’s Multiverse Computing now serves a compressed, proprietary copy of GLM-5.2 from its own API, and it is the best European model on the board.
What changed
Before the table, five things in this snapshot moved the board, and two of them are the answer to the question the last one asked: whether “weights promised” means anything.
Three US flagships shipped in three days. Anthropic shipped Claude Fable 5.1 on 2026-09-01 (Anthropic 2026b), Meta shipped Muse Spark 1.3 on 2026-09-02 (Meta AI Research 2026), and OpenAI shipped GPT-6 Astra on 2026-09-03 (OpenAI 2026). Astra is the generational one: $10 and $50 per million tokens, a 1,050,000-token context window, and the first OpenAI model to cross the Critical cybersecurity threshold of OpenAI’s own Preparedness Framework. On the new index it grades 52.8, 0.6 behind Fable 5.1 at 53.4, with Spark 1.3 third at 48.2. All three are proprietary API rows. The top of the board is one week of US releases.
The scale itself changed, twice. AA shipped v4.2 on 2026-09-04, with harder tasks, roughly 40 percent of the composite graded on private test sets so nobody can study to the exam, and a new agentic knowledge-work evaluation called AA-Briefcase. Then v4.3 upgraded Terminal-Bench to v4.0 and added AutomationBench-AA, which brings the composite to ten evaluations (Artificial Analysis 2026a, 2026b). Every number on the board moved, and by different amounts, because the new tasks hit different capabilities. The top went from 63.1 (Opus 5, on v4.1) to 53.4 (Fable 5.1, on v4.3). DeepSeek fell much harder than Kimi did. Scores from different index versions are not comparable. So this snapshot I read the gaps and ignore the levels.
The GLM-5.3 weights landed. On 2026-08-28, the day they were due, Z.ai published the full weights on HuggingFace under a custom permissive license, 744B total parameters with 40B active, FP8 and BF16 artifacts included (Z AI 2026a). That was the promise the last snapshot was watching. It held. Z.ai delayed the release once, for the model’s own cyber capability, and then delivered on exactly the day the revised schedule named. With the weights out, the API model and the downloadable model are the same thing, and GLM-5.3 at 44.9 is the leading open-weights model on the board, past Kimi K3 at 43.8 for the first time. One more thing worth noticing, because it happened in the same two weeks. OpenAI rated GPT-6 Astra past the Critical cybersecurity threshold of its own Preparedness Framework, three weeks after Z.ai’s cyber delay (OpenAI 2026). The strongest labs on both pillars are now shipping exploit-grade capability in the open. Neither of them treated that as a reason to keep the weights back.
The Qwen Max promise is six weeks old. The hybrid was promised “within days” on 2026-08-03. Six weeks later there’s still no model card on HuggingFace. What Alibaba shipped instead, on 2026-09-02, was a dated API refresh, Qwen3.8-Max-0902, while the open 2.4T-A95B core sits where it has sat since 2026-08-12 (Alibaba 2026b). The open 2.4T sibling grades 40.0 against the closed endpoint’s 40.3. The remaining 0.3 is a licensing choice, in its sixth week. The open line under Max is still doing its job: Flash-Next is the open preview of the Qwen4 architecture, the same role Qwen3-Next played for Qwen3.5 (Alibaba 2026a). Set the two Chinese labs side by side. Z.ai promised, delayed for safety, delivered on the day it named. Alibaba promised, shipped everything below the Max line, stamped a new date on the API, and went quiet on the checkpoint. One promise kept, one promise gone quiet. That difference is the whole “Open?” column in miniature.
Now the European news. On 2026-09-02 Multiverse Computing launched Quasar 438B, a proprietary model served from their CompactifAI API, announced as “Europe’s leading AI model” (Multiverse Computing 2026b). It grades 27.1, the first European model above Mistral on this board. The label is the problem. AA lists it as “Quasar 438B (max, based on GLM-5.2)” (Artificial Analysis 2026f). The launch post did not name a base model. The technical note Multiverse published the next day, after the Spanish press asked, does: “Quasar 438B is a compressed model built from GLM-5.2, the open-weights model from Z.ai”, pruned from 265 to 148 experts per layer (Multiverse Computing 2026a). On the index AA was running at launch, the open GLM-5.2 original beat the compressed proprietary copy 53 to 43. On today’s v4.3 the open original (34.0) still leads the copy (27.1) by 6.9 points. So the first European model to top Mistral on this board is a for-profit compression of a Chinese open model, scoring 6.9 points below the original. That is the same dependency with a European invoice.
Two structural notes round it out. Google fell out of the frontier window. Its newest model, Gemini 3.8 Flash (2026-09-02), grades 41.2, and nothing Google grades within ten points of the top right now (Artificial Analysis 2026e). DeepSeek’s best graded variant sits at 39.5, also below the cutoff. DeepSeek did answer inside the snapshot window: on 2026-09-10 it shipped V4.1-Flash, open weights under MIT, the first of a new Causal Encoder-Decoder architecture family, 552B MoE with native vision, positioned as the temporary home for V4 Pro API traffic while a V4.1 Pro is prepared (DeepSeek 2026). AA graded it at 39.5 on the day it shipped, DeepSeek’s best score on v4.3 and still 3.9 points under the window. V4.1 Pro is the row I am watching. The August footnotes also slipped under the new scale: Sapiens’ Agnes 3.0 Flash (35.5, shipped 2026-09-11) and Korea’s Motif 3 (33.6) are below the window (Sapiens AI 2026; Motif Technologies 2026). One new lab appeared under it this round: MBZUAI’s K2 Horizon from the UAE, 25.7 for the 36B model on 2026-09-03.
One structural change, added 2026-08-24. The table is now generated straight from the Artificial Analysis Data API instead of a hand-kept list: every lab’s best model qualifies automatically when it lands within ten points of the top, and every European lab is on the board no matter what it scores. The Grok 4.6 miss cannot happen again. It also means the board grew two European rows that snapshot: Multiverse Computing’s HyperNova 60B (18.3) and the Swiss AI Initiative’s Apertus 70B (2.0). Neither is anywhere near the frontier. That is exactly why they are shown.
The scoreboard
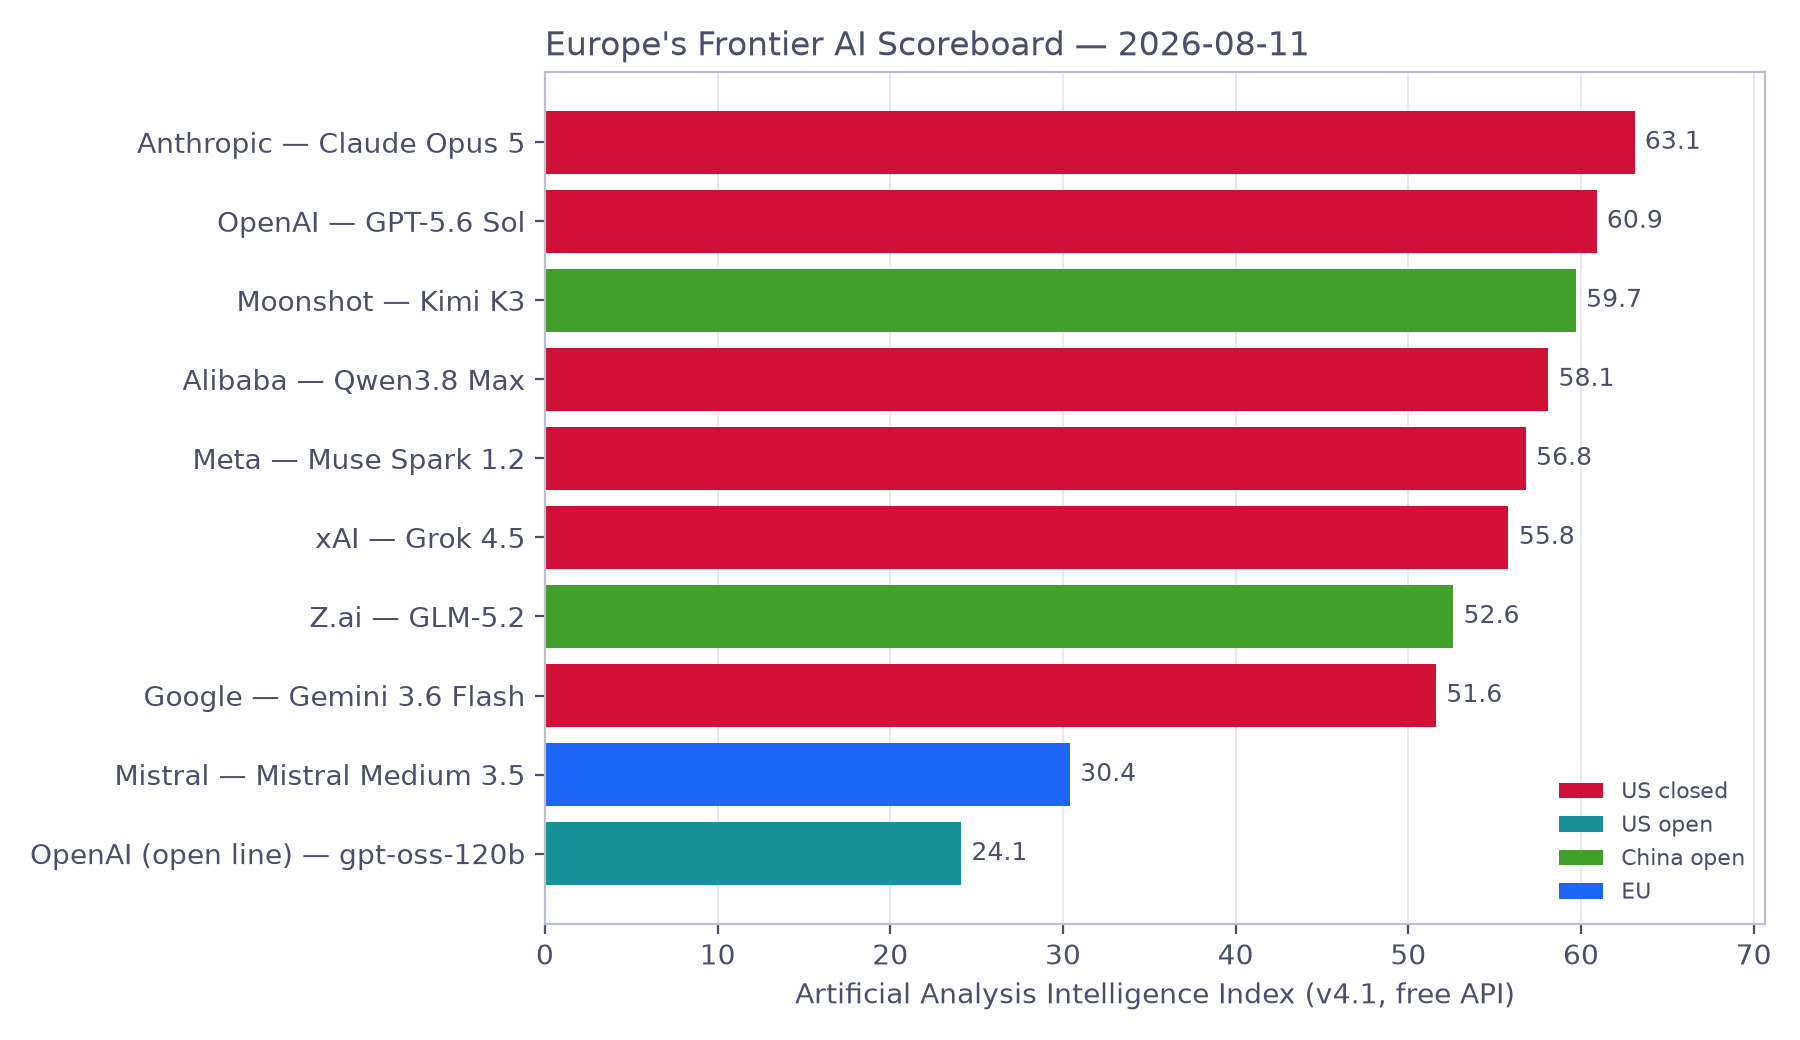
Snapshot date: 2026-09-15. Scores from the Artificial Analysis Intelligence Index v4.3, pulled from their Data API (free tier) (Artificial Analysis 2026d, 2026c). Each row is the top reasoning variant of that lab’s frontier model, selected automatically: a lab enters when its best model is within ten points of the board’s top score, European labs enter regardless of score, and the curated open-line rows carry the open-weights argument. The Δ top column is each row’s distance from the board’s best score, because the comparison to the frontier is what the table is for. Treat every number as a point-in-time reading. One note before you compare this table to the last one. The index was rebuilt twice since 2026-08-28, so every score on this page is on the v4.3 scale and none of them are comparable to the numbers in any earlier snapshot. The Δ top column and the ordering are the comparable quantities.
| Rank | Lab | Region | Latest frontier model | Open? | AA index | Δ top | EU access | Verdict |
|---|---|---|---|---|---|---|---|---|
| 1 | Anthropic | US | Claude Fable 5.1 | Proprietary | 53.4 | 0.0 | API | Revocable (ToS and political risk) |
| 2 | OpenAI | US | GPT-6 Astra | Proprietary | 52.8 | −0.6 | API | Revocable |
| 3 | Meta | US | Muse Spark 1.3 | Proprietary | 48.2 | −5.2 | API | Revocable (Meta closed its frontier) |
| 4 | Z.ai | China | GLM-5.3 | Open weights (custom permissive license, shipped 2026-08-28) | 44.9 | −8.5 | Self-host | Revocable (Beijing consulting export limits) |
| 5 | xAI | US | Grok 4.6 | Proprietary | 44.4 | −9.0 | API | Revocable |
| 6 | Moonshot | China | Kimi K3 | Open weights | 43.8 | −9.6 | Self-host | Revocable (Beijing consulting export limits) |
| 7 | Alibaba (Flash-Next open) | China | Qwen3.8-Flash-Next | Open weights (Qwen community license) | 39.9 | −13.5 | Self-host | Revocable (Beijing consulting export limits) |
| 8 | Alibaba (27B open) | China | Qwen3.8-27B | Open weights (Apache 2.0) | 33.9 | −19.5 | Self-host | Revocable (Beijing consulting export limits) |
| 9 | Multiverse Computing | EU | Quasar 438B | Proprietary (AA: based on GLM-5.2) | 27.1 | −26.3 | API | EU pillar, under construction, far from frontier (AA: GLM-5.2 derivative) |
| 10 | Mistral | EU | Mistral Medium 3.5 | Open weights | 14.9 | −38.5 | Self-host | EU pillar, under construction, far from frontier |
| 11 | OpenAI (open line) | US | gpt-oss-120b | Open weights | 12.3 | −41.1 | Self-host | Stable, but far from frontier |
| 12 | Swiss AI Initiative | Europe (non-EU) | Apertus 70B Instruct | Open weights | 5.1 | −48.3 | Self-host | European, outside EU jurisdiction |
| n/a | EUROPA / Domyn | EU | In training | TBD | TBD | TBD | EU native | Under construction, >400B params, 24 EU languages |
A few cells deserve footnotes. The GLM-5.3 row is the headline this round. The weights shipped on 2026-08-28 on the schedule Z.ai named when it delayed them, so the flagship row is an open-weights row, and the best open-weights model on the board is Chinese at full strength, 44.9 against Kimi K3’s 43.8. Kimi K3 held that lead for six weeks (Z AI 2026a, 2026b). The Qwen family still spans four openness states: a closed Max endpoint (40.3, below the window this round), an open 2.4T sibling (40.0, within 0.3 of the closed endpoint), an open Flash-Next architecture preview on the Qwen community license (39.9), and an Apache 2.0 consumer 27B (33.9), with the Max hybrid six weeks past its launch-day promise (Alibaba 2026b, 2026a). The Multiverse cell is a new kind of openness problem. Proprietary, based on GLM-5.2, and served from Spain (Artificial Analysis 2026f). And the gpt-oss-120b row is still there to make a point. An open-weights model that grades 12.3 is a research artifact. You cannot run a continent on it.
How to read it
A few things the table does not show on its own.
The AA index moves week to week as it re-aggregates, and this round it was rebuilt twice. Intelligence Index v4.3 aggregates ten evaluations (AA-Briefcase, GDPval-AA v2, AutomationBench-AA, Terminal-Bench v4.0, SciCode, Humanity’s Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1), and roughly 40 percent of the composite is now graded on private test sets (Artificial Analysis 2026a, 2026b). A model can gain or lose a point or two without a new release, just because the index re-sampled. It can lose a lot more when the yardstick gets replaced. So a point or two between the rows at the top of the board is noise. The signal is which labs are within shouting distance of the frontier top, and which access regime they ship under. The frontier window now closes after row 6, Kimi K3 at 43.8. Google (41.2), Alibaba’s closed Max endpoint (40.3), and DeepSeek (39.5) all sit below it. The rows underneath are curated open lines and the European watch.
“Open?” is the column that matters most for Europe, and it is the one most likely to lie to you. This round it carries one promise kept and one promise gone quiet. The GLM-5.3 cell used to be a date. It is now a receipt. The Flash sibling has been open under MIT since 2026-08-26, and the full 5.3 weights landed on HuggingFace on 2026-08-28, on the two-week schedule Z.ai announced up front (Z AI 2026a, 2026b). The Qwen cell is still a promise: the Max hybrid was promised “within days” on 2026-08-03, and six weeks later the model card is still not on HuggingFace, while everything below the Max line (2.4T, Flash-Next, 27B) is open and a dated API refresh shipped instead (Alibaba 2026b). Alibaba fenced its Max tier across two generations (Qwen3.7-Max proprietary, Qwen3.8-Max paid preview), and the 2026-08-13 open-weighting of the 2.4T-A95B broke the pattern for everything except the top. The 27B cell is the one with no promise and no asterisk. Apache 2.0, on HuggingFace, downloadable today.
“EU access” sounds like a yes/no question. It is not. API access means you can call the model today and you cannot run it yourself tomorrow if the provider decides you should not. Self-host means you have the weights on hardware you control, and the only thing that can take that away is a license change you can see coming or a jurisdiction deciding to restrict exports. The two are different kinds of access, even though both let you do inference right now.
Where Europe sits
The European rows are the ones I care about most, and this round the order among them changed.
Multiverse Computing is now the best-graded European lab, and the row is worth reading twice. Quasar 438B (27.1, ranked #105 among all graded variants) is proprietary, served from Multiverse’s own CompactifAI API, and, by Multiverse’s own technical note, “a compressed model built from GLM-5.2”, the Chinese open-weights model, pruned with their quantum-inspired method (Multiverse Computing 2026a; Artificial Analysis 2026f). At launch Multiverse billed it as Europe’s leading AI model. That is technically true, and it is the wrong lesson. The open GLM-5.2 original outscores the compressed European copy of itself by 6.9 points on the current index, and the original is free to self-host while the copy is API-only. Their previous graded model, HyperNova 60B, is the same pattern: AA labels it “based on gpt-oss-120b”, the American open-weights artifact. Both of Multiverse’s graded rows are compressions of other labs’ open models. That is a real business, and it is a long way from a frontier.
Mistral is still the closest thing Europe has to a frontier lab, and the ASML-led 1.7 billion euro Series C put real compute behind that (CNBC 2025). It is now the second-best European lab on this board. Mistral Medium 3.5 grades 14.9 on v4.3, ranked #252, 38.5 points off the top, and nothing Mistral has shipped since April grades above it. The frontier-tier question (does Mistral ship a model that sits in the top three of the AA index, ever) is still open. Mistral is the European pillar under construction, and “under construction” is still the generous reading. As of this snapshot it is also no longer the European lead.
The EUROPA consortium led by Domyn is the other one to watch, and it is unchanged. The EU Frontier AI Grand Challenge is funding a >400 billion parameter model trained on all 24 EU languages on a 6,000-chip Nvidia Blackwell cluster (European Commission 2026). It is still the only announced European project that names the frontier tier as the goal instead of using it as a slogan. It is also not a frontier model yet, and the gap between “we are training a 400B model” and “we have a model in the top three of the AA index” is exactly the gap Europe has been failing to close for two years.
The bottom European row is there to show the depth of the field. Apertus 70B (Swiss AI Initiative, 5.1, ranked #612) is real, downloadable, European, and 48.3 points off the frontier. Depth matters. Europe’s third-best graded lab is not close to Europe’s best, and Europe’s best is a compressed copy of somebody else’s model.
There is still no European row in the top half of the table. The best European variant sits 26.3 points off the top, ranked #105 once every graded variant is counted. That is the scoreboard.
What would change the table
A few specific things would force an update beyond the normal score drift:
- DeepSeek V4.1 Pro ships. DeepSeek’s best graded model is below the window for the first time since this board started, and the first answer shipped inside this snapshot: V4.1-Flash, open weights, MIT, a new architecture family, on 2026-09-10 (DeepSeek 2026). It graded 39.5, 3.9 under the window. If V4.1 Pro lands anywhere near the window, DeepSeek is back.
- Qwen3.8-Max hybrid weights actually ship. Six weeks and one dated API refresh later, still no model card. Z.ai has now kept a dated weights promise; Alibaba’s is the standing counterexample. I will believe the hybrid when the model card lands on HuggingFace.
- Qwen4 ships. Flash-Next is still the only open preview of the Qwen4 architecture. If Qwen4 lands as a Max-class open drop, the top of the board is in play. If it lands API-only with open siblings below, the Qwen pattern repeats at the next generation.
- Beijing formalizes the overseas-access restrictions it has been consulting on. The reporting now says the Ministry of Commerce is drafting a tiered export regime that would treat Qwen and DeepSeek weights the way Washington treats advanced chips (The Next Web 2026). Several Chinese rows flip their verdict from “Revocable” to “Restricted” and pillar two gets measurably weaker for Europe.
- A US provider changes terms in a way that breaks EU access (region lock, use-case restriction, government-mandated cutoff). The corresponding US row gets a date stamped on its verdict.
- Google ships something that re-enters the frontier window, or Mistral or EUROPA publishes a model that lands in the AA index top ten. A row leaves or joins the board.
- Meta re-opens a frontier-tier Muse Spark with open weights, or OpenAI ships an open-weights model above 40. The US regains an open-weights frontier leg, and the two-pillar story gets a third leg I did not expect.
- A new lab enters the frontier window. The table grows a row. Multiverse did this round, with a compression of someone else’s open model. I would rather the next one arrive the normal way.
If none of those happen, the table still moves, because the AA index moves. That is kind of the point of a living scoreboard. The structure stays stable.
How this post will live
I will update this post in place. The snapshot date at the top of the scoreboard section is the version.
The argument will not change much. The two-pillars thesis has aged the way I feared, and the scoreboard is the receipt. What changes is the receipt. New models, new scores, new access regimes, new European rows (I hope).
If you spot a number that is wrong, or a question mark you can fill, reach out. I would rather have a scoreboard with real gaps than one with confident mistakes. The whole point of publishing this is that the picture moves, and I am one person with one reading of it. The numbers this round come straight from the Artificial Analysis Data API, so at least the arithmetic is not mine to get wrong.
Conclusion
I started writing about European AI sovereignty because I kept noticing the same thing every time a frontier model landed. The good news was always about someone else’s model. The bad news was always about someone else’s decision. Europe’s role in the story was to read the announcement and adjust its compliance documentation.
The scoreboard makes that visible in one place. Nine of the twelve scored rows are non-European. The European rows start 26.3 points below the frontier and fall away from there. Everything in between is the access regime we rent from people who owe us nothing. The one piece of good news in the structure is that the open-weights frontier is genuinely competitive right now, and this round its strongest model finally shipped at full strength: GLM-5.3, weights out on the day promised, grades 44.9, ahead of Kimi K3, ahead of the whole open Qwen line, and ahead of every US flagship except the top three. The bad news attached to it is that the open frontier near the top is still entirely Chinese, and the exceptions this round are a research artifact and a copy: OpenAI’s gpt-oss-120b at 12.3, and Europe’s own best entry, a proprietary compression of a Chinese open model that scores 6.9 points below the original.
The two promises the last snapshot was watching both resolved, in opposite directions. Z.ai delayed the GLM-5.3 weights for the model’s own offensive capability and then shipped them on the day it had named. Alibaba put a new date on a closed API and let the hybrid promise run past six weeks. A frontier you have to wait for, at the discretion of the lab that trained it, is a frontier you do not own. The closed US frontier is available, three new flagships in three days this round, and it is revocable, as we watched the political risk go concrete in March. The European pillar is under construction, and the newest European model on the board is a rental desk for the other two. It is still the only pillar whose verdict we get to write ourselves.
If you are building one of the European rows, I would like to hear from you. If you think I have the framing wrong, tell me which row and why.